Latest Blog
What Scalable Global Hiring Workflows Have in Common: Five Tests
Researcher
•
5 min read
Share this post


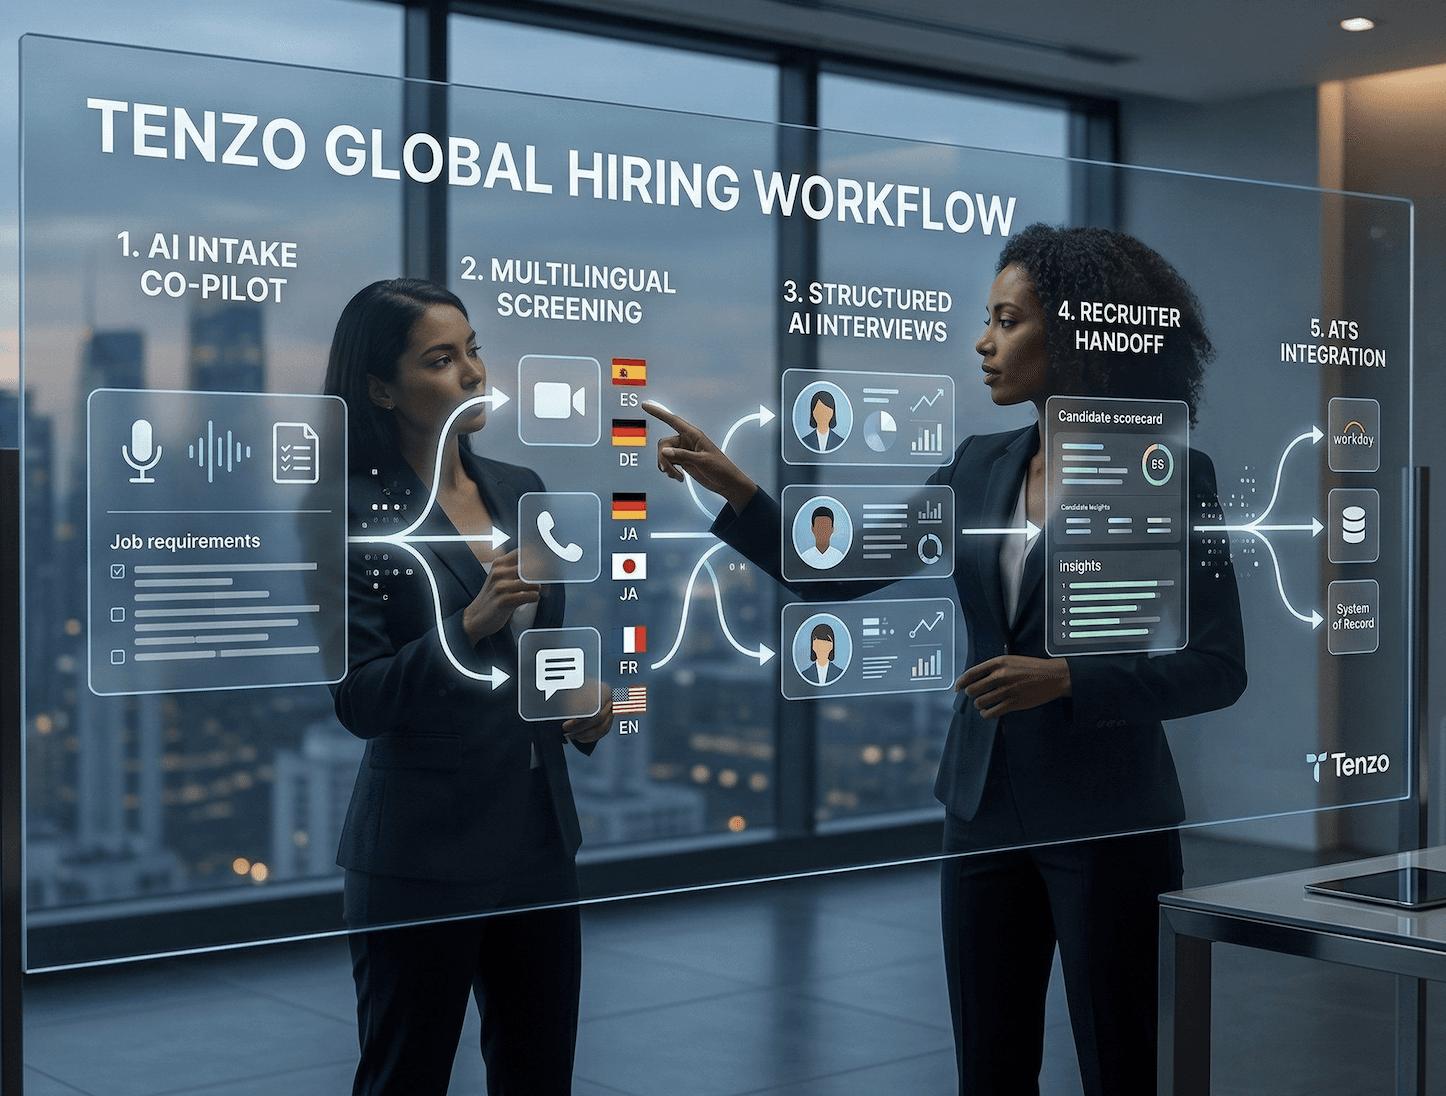
Hiring workflows that hold up across regions share five properties. They make first contact fast enough to reach a candidate while that candidate is still answering anyone at all. They add screening capacity as application volume rises instead of adding recruiters. They handle language in a way somebody has measured on the varieties your candidates speak, rather than on the language codes a vendor lists. They include a review step that recruiters perform, and you can see them doing it in the usage logs. And they keep a record complete enough to reconstruct any single decision six months later.
You can test all five on your own data before a vendor demonstrates anything, and each test gives you a number rather than a direction.
Global programmes rarely break at the interview. They break where volume meets a process designed for one country, and the 2026 benchmark data says fairly precisely where.
Why does application volume, not recruiter speed, set the constraint?
Application volume rose and the share of applicants worth screening did not rise with it. All three sources below are vendors reporting on their own customers. Employ sells an ATS, Criteria sells assessments, Pin sells recruiting outreach. Size the problem with them, don't forecast with them.
Employ Inc.'s 2026 Hiring Benchmarks Report, drawn from over 6,600 companies on Jobvite, Lever and JazzHR and released 7 January 2026, has applications per role up 24% to 257.5 while the qualified-applicant rate stayed flat at 11.5% against 11.6%. The same dataset has application-to-first-screen improving from 8.3 days to 7.2, and time to fill from 67.7 to 63.5. Recruiters got faster and the pile got bigger faster.
Some of the new volume is machine-written. Criteria Corp's 2026 Candidate Experience Report, published 16 March 2026 from over 2,500 job seekers, found 34% have used AI tools to apply. If you scale by adding reviewer hours, then you are adding them against a curve that is steepening. If you scale by ranking résumés faster, then you are sorting a pile whose composition has changed without anybody reading it. Neither operation moves the 11.5%.
The speed target comes from the candidate side. Pin's analysis of over 230,000 outreach threads run between January 2023 and June 2026, published 21 July 2026, puts median time to reply at 3.9 days, with 26% of all replies arriving inside 24 hours, 34.5% inside 48 and 70.8% by day seven. That is one platform's traffic and cannot be audited from outside, so read the shape of the curve and not the decimal places. Read the tail as well as the median. If a third of your total response volume lands in the first two days, a first touch that waits for the next business morning spends that window competing against whoever answered on Saturday.
Test 1. Median hours from application to first contact, split by country and role family, never averaged. Averages hide the overnight and weekend applications, which is where global programmes lose most.
Test 2. Screens completed per recruiter per week, with "completed" defined and agreed before anyone quotes you an improvement.
Book a Volume Baseline Session. Bring last quarter's application counts by market and we will work out which of your regions is already past the point where reviewer hours can keep up.
What does a language boundary cost a workflow?
It costs you the transcript, before it costs you anything else. Every downstream step in a multi-region workflow reads the transcript rather than the candidate. The rubric reads it, the recruiter summary reads it, and so does the comparison against another market's candidates. If the transcript gets a word wrong, then every step after it treats the wrong word as the thing the candidate said.
The size of that error is documented and it is not evenly distributed. Testing five commercial systems, Koenecke et al. found an average word error rate of 0.35 for Black speakers against 0.19 for white speakers, on one language, in one country, from clean recordings. A 2025 sociophonetic analysis of four major commercial systems found the disparity persisting in current models and concluded that "acoustic modeling of dialectal phonetic variation, rather than lexical or syntactic factors, remains a primary source of bias in commercial ASR systems." A problem sitting that deep in the stack is not something a better question set corrects for later. If one country's range of accents produces a spread that wide, then a workflow spanning nine countries is facing a different problem, and it has to be measured country by country.
Test 3. Word error rate per variety, measured on your own recordings: mobile handsets, background noise, hands-free, weak connections. Where you cannot get audio before purchase, ask for the per-variety figures. A vendor who can't produce them probably hasn't measured them. The mechanics of that test, meaning which varieties to sample, how to handle candidates who mix languages mid-sentence, and what to ask about benchmark vintage, are a subject of their own. We have written them up separately in what to test before a multilingual rollout.
Run this test before the other four, because a failure here invalidates everything measured after it, and because the consequence is legal as well as operational. Under 29 CFR 1606.7, "the primary language of an individual is often an essential national origin characteristic," which places a difference in pass rates between language groups inside protected-class analysis instead of inside your operations dashboard. Set the threshold with the rule the enforcement agencies already use. 29 CFR 1607.4(D) says a selection rate below four-fifths of the highest group's will generally be regarded as evidence of adverse impact. Where the mechanism producing that difference is speech recognition performing worse on accented speech, you are looking at a national-origin fact pattern and not a tuning problem.
Bring Us Your Worst Audio. Recordings from the market that worries you most, run in the session, failures shown alongside the averages.
Where do global workflows break after launch?
Five failures show up after launch, and none of them appear in a demo, because a demo has one language, clean audio and a cooperative participant.
Signal | What it usually means | Where to measure it |
|---|---|---|
One region's completion sitting well below the others | The flow assumes a device profile or a working pattern that region does not have | Funnel analytics, split by country and device |
Screens completed rising while submittals stay flat | Capacity moved to a stage that was never the constraint | Stage-conversion report |
Recruiters never opening transcripts | Low trust, or review costs more time than it returns | Product usage logs |
Outcomes landing in the tool and not in the ATS | Field mapping done for the demo tenant and not for yours | Record-level reconciliation, weekly |
Reactivation campaigns producing contacts and no conversations | Stale records, or a channel that market abandoned | Campaign logs against source date |
Test 4. Instrument all five before go-live. None of them requires a vendor's cooperation, and if you don't record a baseline before launch, then when one of these numbers moves in month six you will have nothing to compare it against.
That last row deserves a number of its own. Employ's same 2026 dataset has recruitment marketing email engagement falling to 0.8% from 1.2%. That is corporate in-house list data and not a staffing database, so read across carefully. Any reactivation story resting on email sequences alone rests on a channel that has nearly halved in two years, and reactivation is where global teams most often expect free volume.
Have Us Instrument Your Launch. Bring the five signals above and we will help you define each one against your reporting before go-live, whether or not the tool underneath is ours.
What does a governance trail have to reconstruct?
It has to show which version of which question set a candidate saw, who changed it, and when, six months after the fact and without anyone opening a support ticket. Global programmes strain this harder than single-country ones, because the number of live variants is the number of markets multiplied by the number of times each market asked for a change, and the second figure is never one.
Three regimes make this concrete for a global programme. Recruitment and candidate evaluation are high-risk under Annex III, point 4(a) of the EU AI Act, and those obligations moved from 2 August 2026 to 2 December 2027 when Regulation (EU) 2026/1744 entered into force on 27 July 2026. Article 50 transparency duties were not deferred and have applied since 2 August 2026. Separately, and never deferred, Article 5(1)(f) has prohibited inferring emotions in the workplace since 2 February 2025, which the Commission's guidelines read as covering candidates. Guidelines are the Commission's reading rather than the Article's text, and they do not bind a court. And California's FEHA automated-decision regulations, in force since 1 October 2025, extend liability to an employer's agent and require four years of records, which puts your vendor contract inside your compliance posture instead of beside it.
Test 5. Pick a candidate from a hypothetical audit and ask the vendor to reconstruct the decision in front of you. Ask for the complete list of fields the system infers, including scores no recruiter sees, and read it against Article 5.
Book a Governance Walkthrough. Bring your legal or TA ops lead and we will run test 5 against our own platform.
Where does this approach not work?
There are three cases, and a vendor who cannot name them has not deployed at enough scale to be useful to you.
The first is a market where you cannot verify the language. If your Vietnamese volume is forty candidates a year and nobody on your team can review a Vietnamese transcript, an AI interview in Vietnamese produces evidence you cannot audit. The honest recommendation there is a human screen, not a cheaper one, and we would tell you so instead of taking the market.
The second is roles whose signal is not verbal. A machinist's competence lives in a work sample, a designer's in a portfolio. Structured conversation confirms certifications, availability and shift fit, and it will not tell you whether someone can hold a tolerance.
The third is programmes that cannot instrument themselves. Every one of the five tests assumes your ATS records which country, language and channel a candidate arrived through, and plenty of multi-region stacks do not, because each region was configured separately by whoever set it up. If you cannot split a completion rate by market today, buying software to improve it means buying on faith and finding out in year two. Fix the reporting first. It is cheaper than the pilot and you keep it either way.
Send Us Your Market List. Twenty minutes on which of your markets this suits and which it does not. We expect to rule out at least one, and saying which is the useful part of the call.
Where Tenzo fits
Tenzo runs structured interviews across phone, video and text, sitting alongside your ATS rather than replacing it, with recruiter review over full transcripts, configurable interview design, documented accommodation paths, and version history for audit. Humans review throughout and make all final decisions. Underneath, multiple models run in parallel, for redundancy.
The figure bearing on tests 1 and 2, with its denominator visible: of candidates who apply to a role and are invited to interview, 80% go on to complete an interview. That is completion out of those invited, not out of everyone who applied, which is the flattering denominator of the two. It is also an aggregate, and an aggregate hides the part you need, so split it by country on your own data before you let it mean anything. Average candidate satisfaction is 4.6 out of 5.
On the language side, 10 to 15% of blue-collar interviews run in a language other than English, with Spanish the most common by a distance. Non-English speakers rate the experience higher than English speakers do and opt out less often, which is a qualitative pattern rather than a measured effect, so treat it as a reason to test your own markets and not as a result.
On test 3, a single headline word error rate is the wrong instrument, whoever hands it to you. Word error rate is only interpretable next to the variety it was measured on and the conditions it was recorded in. Averaged across languages, accents and handsets, it converges toward a number every vendor can produce and no buyer can use. The version worth having takes about an hour to produce. In any evaluation we measure per-variety error rates on your own audio, in the session, and show you the failures next to the averages.
To run the five tests on your own markets, book a working session. Bring recordings from your worst one.
FAQ
What do scalable global hiring workflows have in common? They make first contact fast, they add screening capacity as volume rises, they have language performance verified per variety rather than per language, they have a review step recruiters demonstrably use, and they keep a governance trail that can reconstruct any decision. Each of those five has a threshold you can set on your own data before you buy anything.
How fast should a global team make first contact? Faster than the median reply time it is competing with. Pin's 2026 data has 26% of all candidate replies arriving within 24 hours and 34.5% within 48, so a first touch that waits for the next business morning in headquarters time is competing for a pipeline that has already started answering someone else.
Where should a global rollout start? In the market with the highest volume and the least complexity, and in one country rather than three. A first region gives you the baselines the other regions will be compared against, and running two at once means you cannot tell which of the two taught you what.
Who owns the workflow once it spans regions? Somebody named, with authority over the question set. What goes wrong is rarely a bad owner. It is that nobody owns it. Regional teams request variants, each request makes sense on its own, and eighteen months later nobody can say which version any candidate saw.
Does the EU AI Act apply to a global hiring workflow? To the parts touching EU candidates, yes. Recruitment and candidate evaluation are high-risk under Annex III, point 4(a), applying from 2 December 2027 after Regulation (EU) 2026/1744. Article 50 transparency applies now, and the Article 5(1)(f) prohibition on inferring emotions in the workplace has applied since 2 February 2025.